Electron or Tauri 2 and Rust? Desktop Architecture for Local AI
Electron vs Tauri 2 architecture: how to measure RAM, startup time and package size, where Rust's safety guarantees end, and how to plan reproducible local AI benchmarks.
Comparing Electron and Tauri 2 architecture: measuring RAM, startup time and package size, understanding Rust’s safety boundaries, and planning reproducible local AI benchmarks.
In local AI applications, the interface, the inference engine and the models all compete for the same hardware resources. The choice of framework shapes how an application is built, but on its own it does not determine memory usage or processing speed.
1. Measurement status
This article does not publish a verified benchmark of our applications. Earlier figures for memory, startup time, installer size and communication latency have been removed because they lacked raw results, exact build versions and a reproducible scenario. The comparison below describes the architecture; the test protocol is a proposal, not a report of completed measurements.
2. What we are actually comparing
| Area | Electron | Tauri 2 | What to check in your application |
|---|---|---|---|
| Interface runtime | Chromium and Node.js, with a main process and renderer processes | System WebView and a Rust backend | Memory across the full process tree |
| Distribution | Bundles the Electron runtime | Uses the platform’s WebView | Installer, dependencies and models — measured separately |
| Communication | IPC between processes | WebView–backend communication | Actual number of buffer copies and end-to-end operation time |
Tauri does not automatically guarantee lower RAM usage or faster startup for every application. The cost of AI engines, model weights and helper processes must be accounted for independently of the interface.
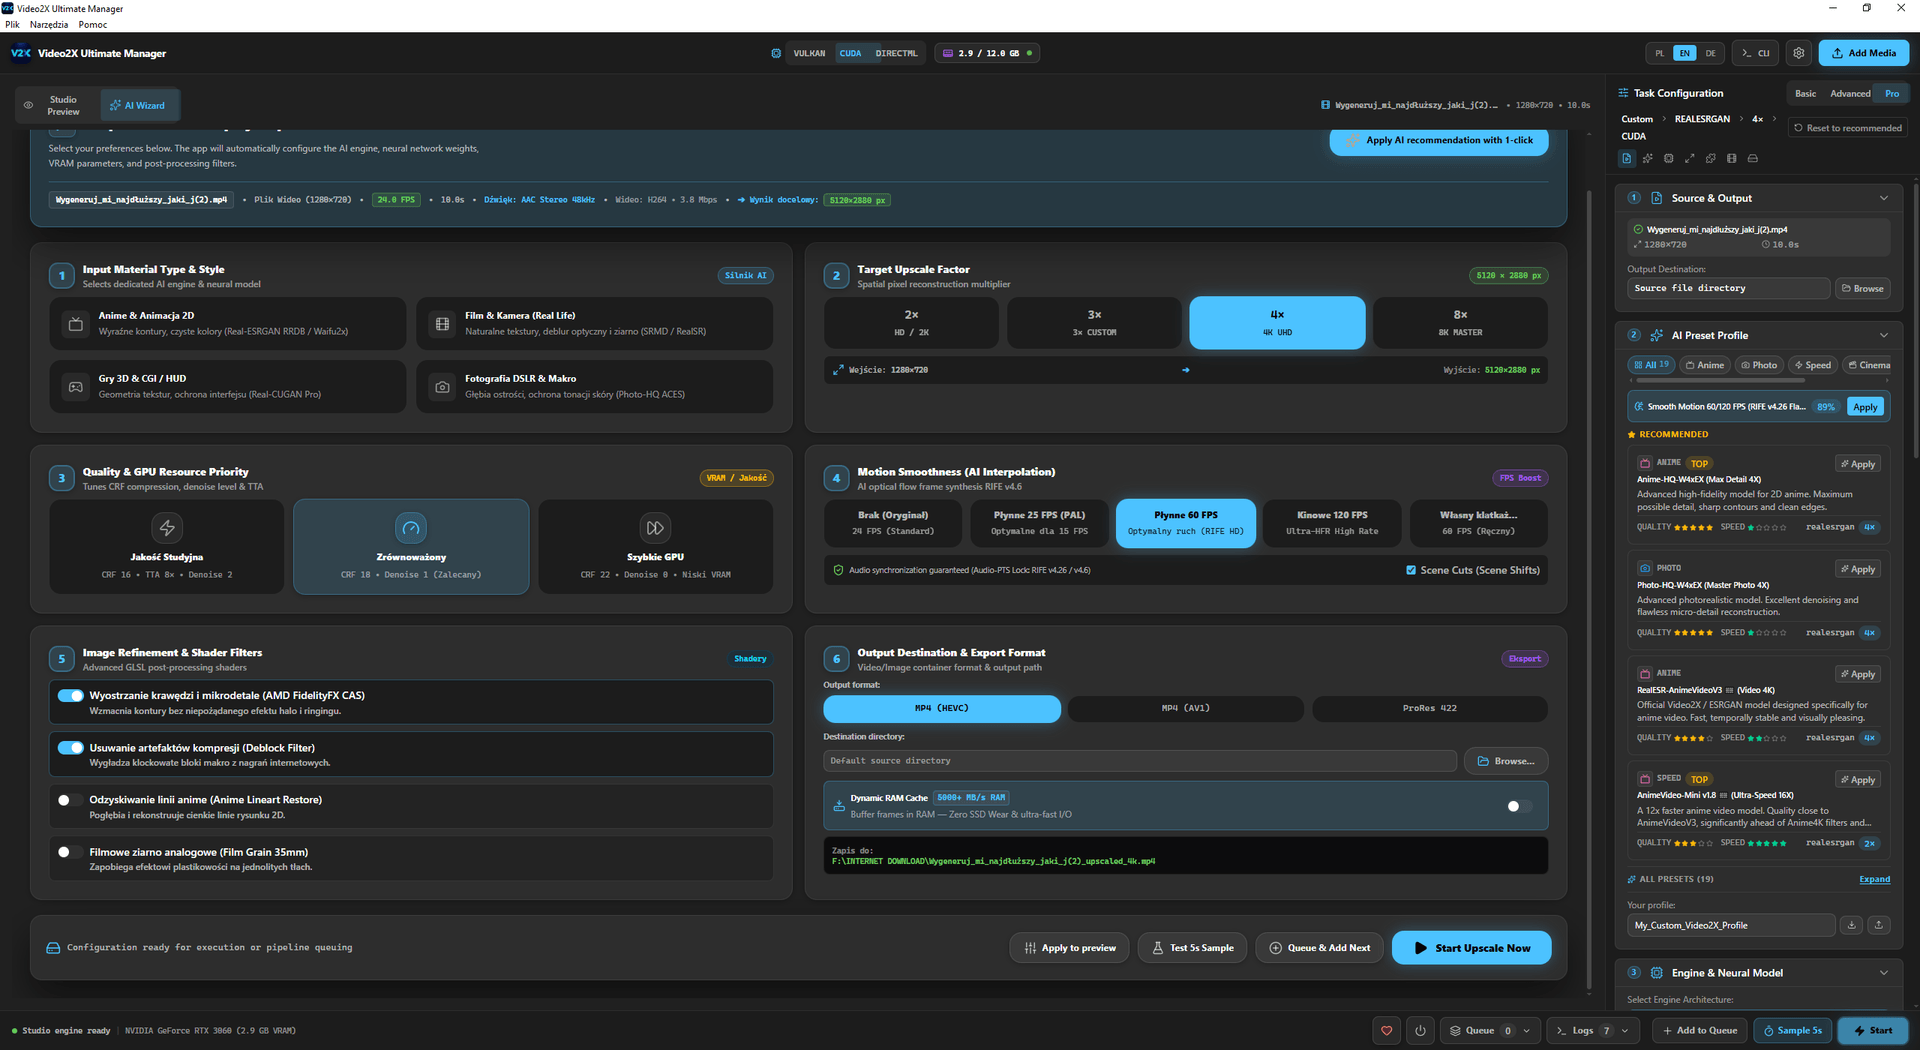
Video2X Ultimate Manager interface
3. Safety and GPU integration boundaries
Safe Rust’s rules prevent certain memory-safety errors and data races, provided that the underlying unsafe abstractions are sound. They do not guarantee freedom from memory leaks, deadlocks or ordering bugs. FFI, C/C++ libraries, drivers and GPU buffer management require separate review.
A native call does not by itself prove zero-copy operation. You need to trace transfers between processes and between RAM and VRAM, as well as buffer ownership and synchronization. We do not present passing a raw address from the interface as a ready-made, safe solution. Command permissions also require a configuration review.
4. Proposed benchmark protocol
- Record the application version, commit, build mode (release), framework, OS and WebView version, GPU driver, CPU, RAM and GPU. Compare equivalent functionality using identical models and input data verified by SHA-256 checksums.
- Test an empty interface, a loaded model and an identical AI task separately. Define the end of startup as the moment the interface is ready to accept a command; measure model readiness separately.
- Run 10 cold-start and 10 warm-start trials. Document how the environment and caches are reset, and keep the two series separate. Record every trial, the median and the range — including failed runs.
- Capture memory for the full process tree and peak usage during the task. State the tool, its version and the memory metric used, and avoid double-counting shared memory. Report VRAM separately. Installer size does not automatically include models or dependencies downloaded later.
- Publish the scripts, commands, CSV results and logs together with the configuration. Only then draw conclusions — limited to the tested hardware and workload.
5. Our products after the migration
Our catalog now runs on Tauri 2: Video2X Ultimate Manager and AI File Sorter have already moved from Electron to Tauri. The exception is VideoSorterLocal — the current version uses PySide6, and its migration to Tauri 2 is in progress. The protocol above still applies, though: switching frameworks does not by itself prove lower memory usage or faster startup — that has to be measured.
Technical sources
These references explain the architecture and its limitations; they do not substantiate performance results for our applications.